Last Updated:
Deepak Singla
IN this article
Explore how AI support agents enhance customer service by reducing response times and improving efficiency through automation and predictive analytics.
Your refund policy changed on Tuesday. By Wednesday, your AI agent was confidently quoting the old one to customers. A new payment rail launched, and three articles on the same topic started contradicting each other. The agent picked one. Sometimes it was wrong. AI support platform regression testing rarely gets discussed at the contract stage, but it separates a safe deployment from a quietly degrading one. Here's what that looks like in practice.
TLDR:
AI support regression is silent: your agent keeps deflecting while accuracy erodes after every policy change.
Static knowledge bases plateau at 30-40% resolution rates because fixes stay trapped in closed tickets.
Safe deployment is not a one-time go-live. It means absorbing policy changes without freezing the agent or blending conflicting articles.
Ask vendors how they define a resolved ticket: deflected queries and end-to-end resolutions are not the same number.
Fini's Knowledge Atlas runs nightly ingestion of escalated conversations, flags article conflicts, and cuts documentation work from 20 hours a week to 2.
What "regression" means in AI support operations
A neobank updates its KYC policy on a Tuesday. By Wednesday, customers are getting flagged for document requirements that no longer apply. The AI agent is still running on last month's playbook, confidently wrong at scale.
That's regression in AI support operations. It has nothing to do with code. It's what happens when your agent's knowledge stops matching reality, and nobody catches it until CSAT drops or a compliance team calls.
Product changes ship. Fee structures update. Refund policies tighten. Each one is a potential gap between what your agent knows and what's actually true. In compliance-heavy industries like fintech and healthcare, that gap is a liability, not an inconvenience. AI support vendors for fintech security handle this differently than general-purpose tools.
Regression is quiet. The agent keeps resolving tickets, deflection numbers look fine, and underlying accuracy erodes week by week until a customer escalates something that should have been routine.
The knowledge death spiral explained
A customer asks why their transfer was flagged. A senior agent figures it out, resolves the ticket, closes it. That fix lives in one closed Zendesk ticket forever.
Next week, the same question comes in. The AI agent has no idea. It escalates again. Another human solves it. Another closed ticket.
Meanwhile, the knowledge base accumulates three articles on international transfers, each with slightly different instructions. The AI picks one. Sometimes it's wrong. Confidence scores drop. The agent starts escalating more, not because the product changed, but because the knowledge is fragmenting under its own weight.
As Gradient Labs notes, AI agents trained only on static knowledge bases plateau at 30-40% resolution rates. That ceiling is a distribution problem: the knowledge exists, trapped in closed tickets and the heads of your best agents.
The Head of CX sees containment holding steady and assumes things are fine. Resolution quality is quietly degrading. The team becomes a documentation factory, and the AI gets dumber while volume keeps growing.
Why policy changes break AI support agents
When a fintech adds a new payment rail, customers ask about settlement times. The AI agent, trained on old documentation, gives the wrong window. Support tickets spike. The knowledge layer didn't move with the product.
Policy changes are the most common trigger. A healthtech company tightens its cancellation window from 48 hours to 24. That single update touches every cancellation article, every agent response, and every escalation path.
A static knowledge layer won't catch the conflict between the old article and the new one. Both stay live. The agent blends them.
Compliance updates hit harder. When a lending product updates its disclosure requirements, the agent resolves tickets using outdated language. In a compliance-driven context, that's a liability, not a support quality issue.
The problem is structural. Most AI support agents treat the knowledge base as a fixed input ingested at setup, a knowledge management architecture problem that predates AI deployment entirely. Product changes happen outside that layer, and the gap widens with every sprint.
Why traditional AI support tools fall short
Most AI support tools respond to change the same way: someone on the ops team notices a wrong answer, files a ticket, rewrites the article, re-tests the flow, and re-deploys. The cycle takes days, sometimes weeks. By then, the agent has already answered that question incorrectly several hundred times.
The mechanics are predictable. An agent flags a bad resolution. A human reviews it. KB articles get updated manually. Someone tests the affected flows. The fix ships. Then another product change happens, and the cycle restarts.
That loop never catches up because product reality moves faster than manual review can track. A team running quarterly tuning cycles is already three sprints behind. The result is not a broken agent but a confidently wrong one. That is harder to catch and more damaging in compliance-sensitive contexts.
The stakes are concrete. According to Digital Applied's 2026 AI statistics report, 71% of CX leaders rank hallucination-related incidents as a top-three governance risk. When comparing AI support platform hallucination benchmarks, manual re-tuning cycles are precisely the environment where those incidents accumulate, because the gap between product reality and agent knowledge is always open.
What a safe deployment actually looks like
Safe deployment in AI support is not a one-time go-live event. It's the ongoing ability to absorb change without breaking what's working.
In practice, that means three things: the agent can take in a policy update without contradicting its existing answers, resolution rates hold steady during and after that update, and the ops team isn't manually stitching the knowledge layer back together.
Most teams handle this by freezing agent behavior during updates. While the freeze is active, customers still ask questions. The agent responds from stale knowledge or escalates everything. Resolution drops. The "safe" approach produces the same regression it was meant to prevent.
A genuinely safe deployment keeps the agent live while changes propagate through a controlled review layer. New articles are surfaced for human sign-off before they go active. Conflicts between old and new documentation are flagged, never blended. The agent's behavior is governed by the latest approved state of the knowledge base.
In compliance-heavy industries, that distinction matters legally. An agent giving answers based on a superseded disclosure policy is a compliance record problem, and the safest AI support vendors for fintech build this into their architecture.
The role of automated knowledge gap detection
Gap detection separates an agent that degrades silently from one that flags its own blind spots before they become customer-facing failures.
When a query comes in and the agent's confidence score falls below threshold, that is more than an escalation. It is a data point. A self-maintaining agent clusters those low-confidence queries, identifies whether they share a topic, and surfaces the pattern as a candidate gap. The data on whether AI can surface knowledge gaps reliably is now fairly conclusive. The agent tells you what it does not know, before a customer finds out the hard way.
The sequence matters here. Unanswered queries accumulate, get grouped by intent, and surface as draft knowledge items for human review. Conflicting articles get flagged before the agent has to choose between them. Policy drift, where the source system has updated but the knowledge layer has not, shows up as a reconciliation task instead of a wrong answer delivered to a customer.
That last part is closest to regression testing in a software context. You catch the gap before it reaches production, not after a failed resolution surfaces in a CSAT score.
Conflict detection and reconciliation in knowledge management
Two articles, same topic, different answers. The agent picks one, or worse, blends both.
In fintech and healthcare, that is a compliance problem before it is a support quality problem. If a lending product has two active articles on refund eligibility, one from before a policy update and one from after, an agent that blends them may promise a refund window that no longer exists. The customer gets a commitment the business cannot honor. Regulators do not grade on a curve.
Conflict detection catches this before any customer sees it. When two articles share intent but contradict on specifics, a reconciliation layer surfaces both for human review and holds the ambiguous answer out of the active response set. The agent flags the conflict and escalates until resolution is reached.
That work happens in a reconciliation dashboard: duplicates, version mismatches, outdated policies still marked active. Fintech support compliance automation depends on exactly this kind of reconciliation layer. Each conflict surfaces as a task, not a silent failure. Once a human signs off on the correct version, the stale article is archived and the agent's response set updates. Every answer traces to exactly one approved article, not a blend of three.
Nightly learning pipelines vs. manual update cycles
Manual Update Cycle | Nightly Learning Pipeline (Knowledge Atlas) | |
|---|---|---|
How gaps are found | Ops team notices a wrong answer and files a ticket | Every escalated conversation is ingested and clustered by intent automatically |
Coverage | Only what someone flagged. Unflagged issues stay broken | Everything that escalated, regardless of volume |
Ops time per week | ~20 hours on documentation | ~2 hours (human review of system-drafted candidates) |
Article conflicts | Agent silently blends conflicting articles | Conflicts flagged in reconciliation dashboard before any customer sees them |
Policy change handling | Someone rewrites and redeploys. The cycle takes days to weeks | New articles surface for human sign-off; stale articles archived automatically |
Scale during product launches | Manual process falls behind | Automated sweep scales with ticket volume |
Manual update cycles have a fixed cost that compounds. Someone on ops reviews escalations, identifies patterns, rewrites articles, tests affected flows, and re-deploys. That process takes hours per week, and it only covers what someone noticed. What nobody flagged stays broken.
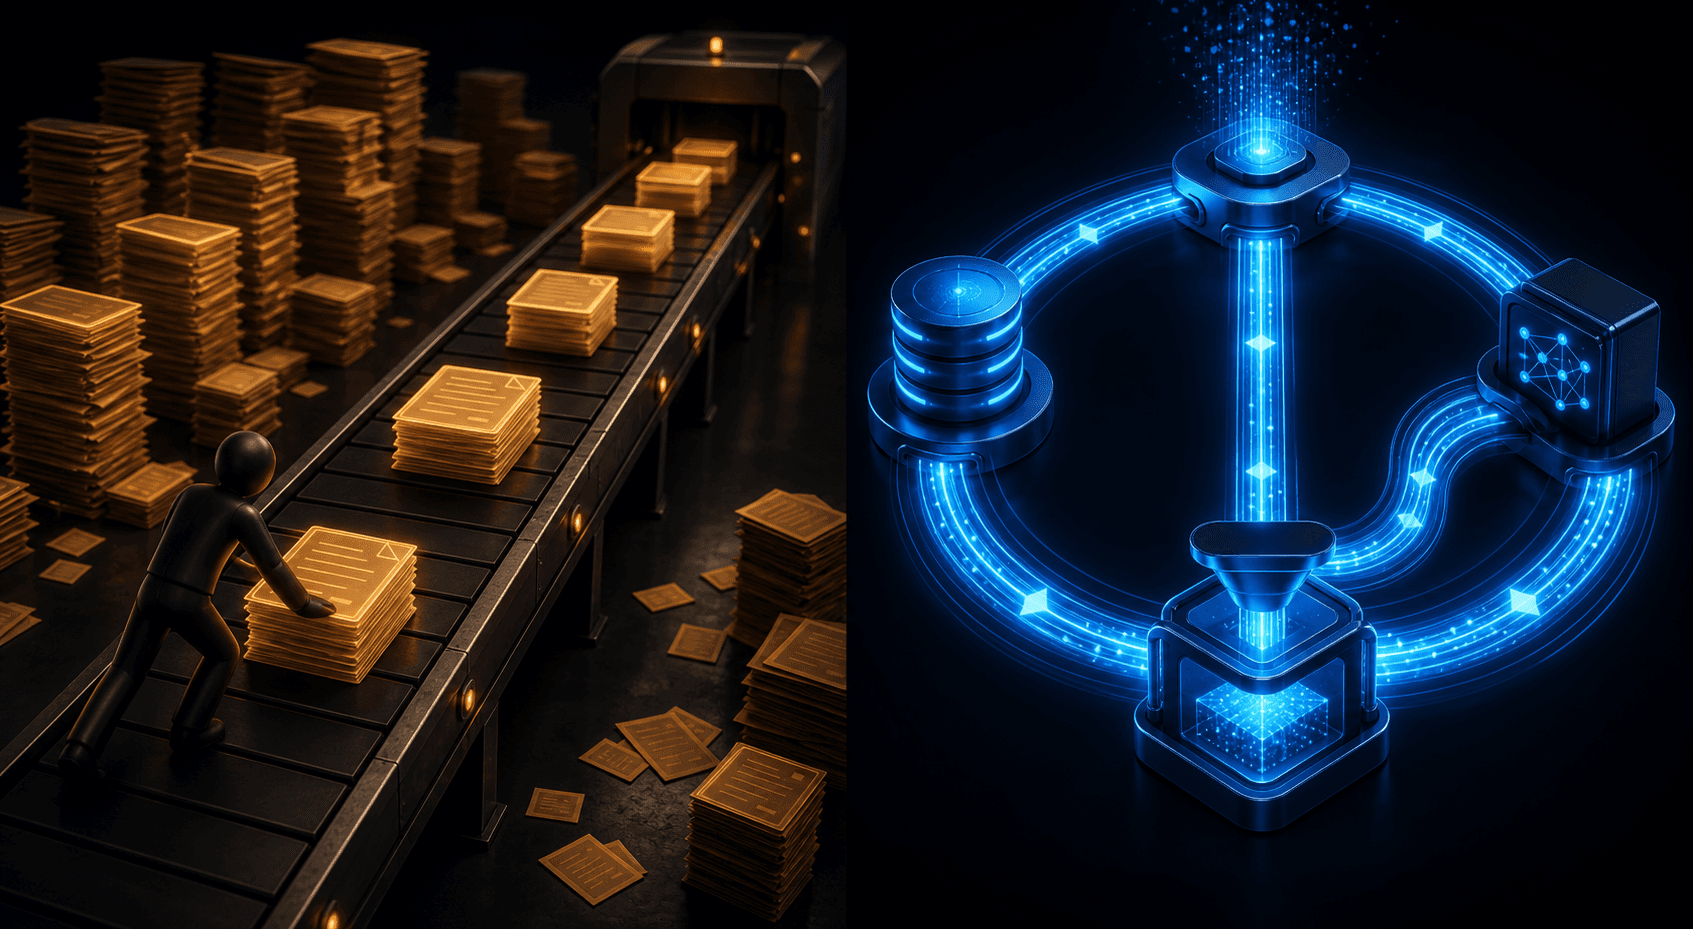
The nightly pipeline runs differently. Escalated conversations get ingested, clustered by intent, and compared against the existing knowledge base. Where a gap exists, the system drafts a candidate article and surfaces it for human review. The reviewer approves, edits, or rejects. Total human time: minutes, not hours.
Coverage is the other gap. Manual cycles catch what ops teams have capacity to review. A nightly pipeline catches everything that escalated, regardless of volume. AI tools for stale and conflicting content make this automated sweep possible. During a product launch or policy change, the automated system scales with it. The manual process falls behind.
Assessing regression resistance before going live
Before signing a deployment contract, run the vendor through this checklist. The questions are process-level, not technical.
Does the agent detect its own knowledge gaps, or does the ops team catch wrong answers manually?
When a policy changes, does it propagate automatically through the knowledge layer, or does someone rewrite and redeploy?
If two articles conflict, does the agent flag the contradiction or pick one and move forward silently?
Does the vendor measure resolution rate or containment? Containment hides wrong answers that technically deflected.
The containment point is the most revealing. An agent optimized for containment can score 80% while quietly giving incorrect answers to a third of resolved queries. Ask how they define a resolved ticket: customer issue closed end-to-end with no human handover, or query deflected without escalation. Only one holds up in a compliance audit. The best AI support platforms for compliance-heavy fintech make this definition explicit before contract.
Beyond definitions, test the behavior directly. Send a batch of real tickets from a recent policy change period and see how the agent handles queries that span both the old and the new policy. If it blends the two, or answers confidently without flagging the conflict, regression resistance is low.
The vendor's answer to "what happens when our refund policy changes next month?" tells you most of what you need to know.
Knowledge ingestion and pre-deployment content quality
Most teams spend weeks cleaning their knowledge base before an AI deployment: scrubbing old articles, deleting duplicates, resolving conflicting policies. The assumption is that the agent needs clean input to produce clean output.
That assumption is partly a trap. No knowledge base arrives in perfect shape, and waiting for perfect means waiting indefinitely.
The more useful question is what the agent does when it encounters messy content. An agent that flags conflicts during ingestion surfaces the cleanup work as an ordered task list, not a precondition for going live. How you train AI on company knowledge determines whether that ingestion step finds problems or buries them.
During ingestion, the agent should identify duplicate articles, mark contradictory instructions, and hold ambiguous content out of the active response set until a human signs off. The output is a reconciliation queue, not a broken deployment.
You can go live with a knowledge base that has problems, provided those problems are visible and managed. What you cannot do safely is go live with an agent that blends conflicting articles silently and delivers a confident wrong answer with no flag raised.
How Fini's Knowledge Atlas prevents support regression
Knowledge Atlas runs a nightly pipeline that ingests every escalated conversation, clusters queries by intent, identifies where the knowledge base has no answer, drafts a candidate article, and surfaces it for human review. Your ops team approves or edits. The fix goes live. Total human time: closer to 2 hours a week, not 20.
Three mechanisms work together here. When a human agent resolves an escalation, Atlas extracts the solution, formats an article, and files it in the correct branch of the knowledge tree automatically. When two articles contradict each other, Atlas flags both in a reconciliation dashboard as a task, not a silent blend into a confident wrong answer. Every response traces to exactly one approved source article.
That architecture drove Atlas from 15% to 70% automation on key support journeys without manual re-tuning between those two numbers. At 3M+ monthly resolutions across fintech and healthcare, that loop has been validated at the scale where a wrong policy answer carries regulatory consequences, well beyond a CSAT dip.
Final thoughts on regression-resistant AI support agents
Policy changes, product updates, and conflicting documentation will keep coming, and your agent's accuracy depends on how fast the knowledge layer catches up. A nightly pipeline that drafts gaps, flags conflicts, and surfaces them for human sign-off beats a manual review cycle that only covers what someone noticed. Your ops team gets to spend 2 hours a week on knowledge, not 20. Book a quick call to see what that looks like on real ticket volume.
FAQ
Should I clean up my knowledge base before going live with an AI support agent, or can the agent handle messy content?
You can go live with an imperfect knowledge base, provided the agent flags conflicts during ingestion instead of silently blending them. Fini's Knowledge Atlas identifies duplicate articles, marks contradictory instructions, and holds ambiguous content out of the active response set until a human signs off, producing a reconciliation queue instead of a broken deployment. What you cannot do safely is go live with an agent that delivers a confident wrong answer from two conflicting articles with no flag raised.
Is Zendesk's native AI good enough now, or do I still need a separate AI agent layer on top?
Zendesk's native AI handles deflection reasonably well, but deflection and resolution are different metrics. If your agent scores 80% containment while quietly giving incorrect answers to a portion of those contained queries, that number lies, and in fintech or healthcare it carries compliance risk. A separate autonomous layer like Fini operates as a dedicated agent seat inside Zendesk, resolves tickets end to end with a full audit trail on every decision, and runs a self-maintaining knowledge loop that Zendesk's native tooling does not provide.
How do I test AI support safe deployment before going live with a policy or product change?
Send a batch of real tickets from a recent policy change period and watch how the agent handles queries that span both the old and the new policy. If it blends the two, or answers confidently without flagging the conflict, regression resistance is low. A reliable AI customer support QA suite catches this before production: new articles surface for human sign-off, conflicting articles get flagged in a reconciliation dashboard, and every response traces to exactly one approved source, never a blend.
Sierra vs Decagon vs Fini for enterprise support in compliance-heavy industries: what actually separates them?
Sierra and Decagon are capable agent frameworks, but neither ships with the compliance posture fintech and healthcare require from day one. Fini goes live in 14 days with SOC 2 Type II, PCI DSS Level 1, ISO 27001, GDPR, HIPAA-compliant, and BAA-eligible certifications already in place, a full decision audit trail on every resolution, and a self-maintaining knowledge layer built around compliance-driven use cases. The benchmark that separates them is not the demo: it is what happens to resolution rate and accuracy after your refund policy changes next month.
What does AI support platform regression testing actually look like in a nightly knowledge pipeline?
Escalated conversations get ingested, clustered by intent, and compared against the existing knowledge base each night. Where a gap exists, the system drafts a candidate article and surfaces it for human review before anything goes live. Conflicting articles are flagged as reconciliation tasks, never delivered as blended answers. Fini's internal benchmarks put manual tuning cycles at roughly 20 hours per week on documentation; with Knowledge Atlas running nightly scans, that drops to around 2 hours.
Related guides
Explore the guide topics to find more reading.
Co-founder